A model can achieve a strong overall score while making the mistakes your organization cares about most. Before comparing percentages, decide which errors are inconvenient and which could cause a serious operational problem.
A practical example
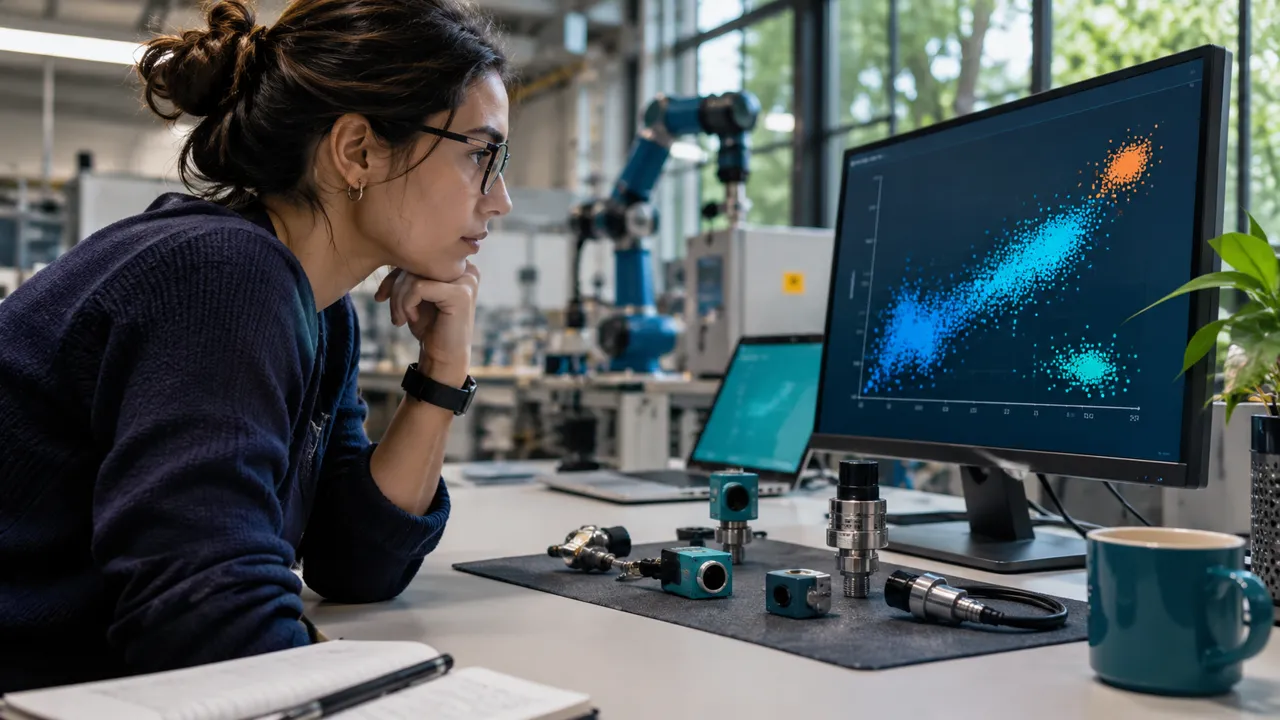
An inspection model used on a production line may encounter far more acceptable parts than defective ones. A single aggregate score can conceal how often defects are missed. Ask for the separate outcomes, the evaluation sample and examples of borderline cases.
What to check
- Request results for each relevant class rather than only an overall figure.
- Separate missed cases from false alarms and explain who handles each.
- Check that evaluation examples resemble the inputs expected after deployment.
The trade-off
A stricter decision threshold can change the balance of mistakes. The choice should reflect the task and the review capacity available, with results monitored as inputs or operating conditions change.
Research context
Google’s Machine Learning Crash Course explains classification measures including precision and recall. These definitions help distinguish different kinds of model error; the appropriate operating threshold depends on the application.
Read the original reference material. The practical examples and evaluation questions above are TheTechGlow’s editorial application of the topic, not reported results from a product test.
Explore Machine Learning for topic coverage, or continue to Artificial Intelligence & Automation for the wider sector.
References and further reading
- developers.google.comhttps://developers.google.com/machine-learning/crash-course/classification/accuracy-precision-recall